AI Infrastructure · Self-hosted LLM · 2026
Local AI Gateway
One 27B vision-language model on a Mac Studio, shared fairly by every app on the machine through an Ollama-compatible API.
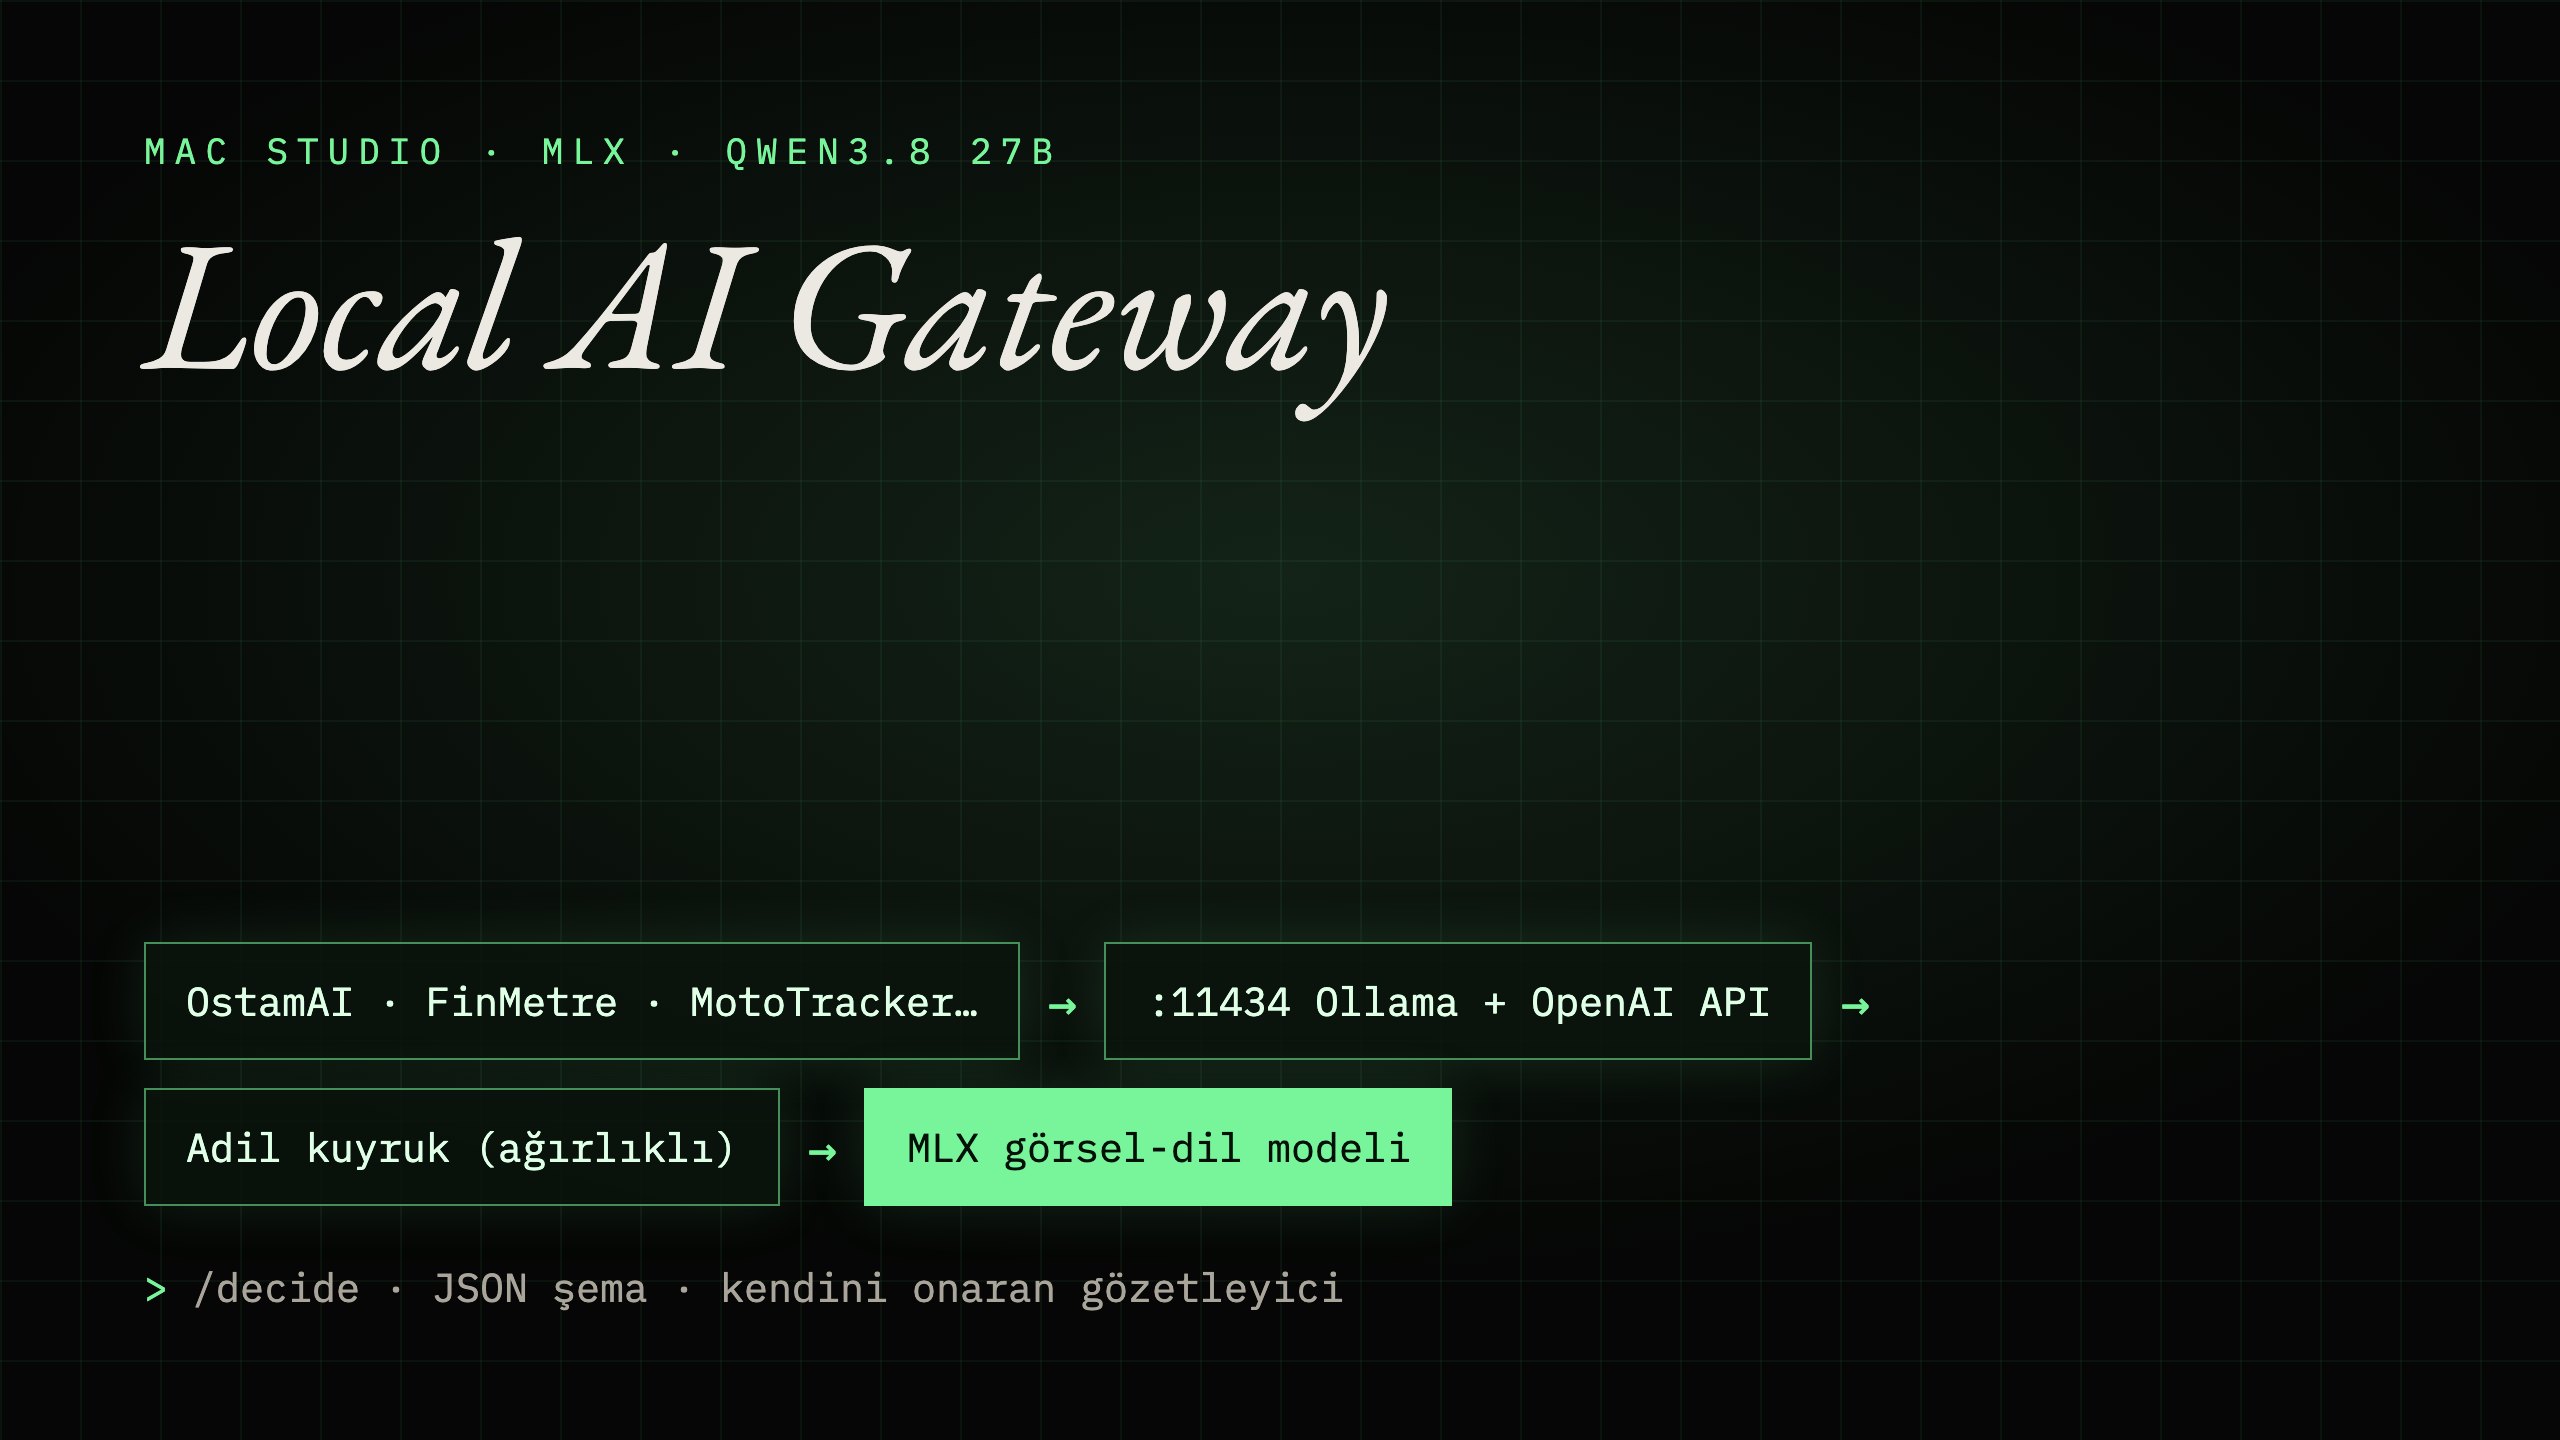
A gateway that replaced Ollama on this machine without any app noticing: the same API on the same port, plus OpenAI-compatible endpoints. Behind it, a 4-bit Qwen3.8 27B model on Apple’s MLX serves text and images from one server, and every client gets a fair share of the queue.
The Problem
Several AI products on one machine — OstamAI, FinMetre, MotoTracker and others — all wanted the same large model. One busy app could starve the others, a hung model blocked everyone, and apps that needed strict JSON or images each solved it differently.
The Solution
A single gateway in front of the model: apps keep calling the address they always used, are told apart by a header or by port, and share the model through a weighted fair queue. JSON schemas are enforced centrally and a watchdog restarts the model if it stops answering.
What I Built
- →Ollama API and OpenAI /v1 on the same port — no app had to change
- →Weighted fair queue per client; abandoned requests give their slot back
- →Text, images and decisions served by one MLX vision-language server
- →JSON and JSON-schema output validated, with one corrective retry
- →A /decide endpoint that answers yes/no, choice and score questions from next-token probabilities
- →Watchdog probes and restarts the model after a stall; upstream timeouts free stuck slots
Highlights
- →Drop-in Ollama + OpenAI API
- →Fair queue per app with weights
- →Self-healing watchdog
Outcome
- →Every AI product on the machine shares one 27B model without starving each other
- →Five typed decisions come back in roughly 5–7 seconds through /decide
- →Rollback to plain Ollama is a documented three-command switch
Related Projects
OstamAI
SaaS · AI Service Management
FinMetre
Fintech · Calculation Platform
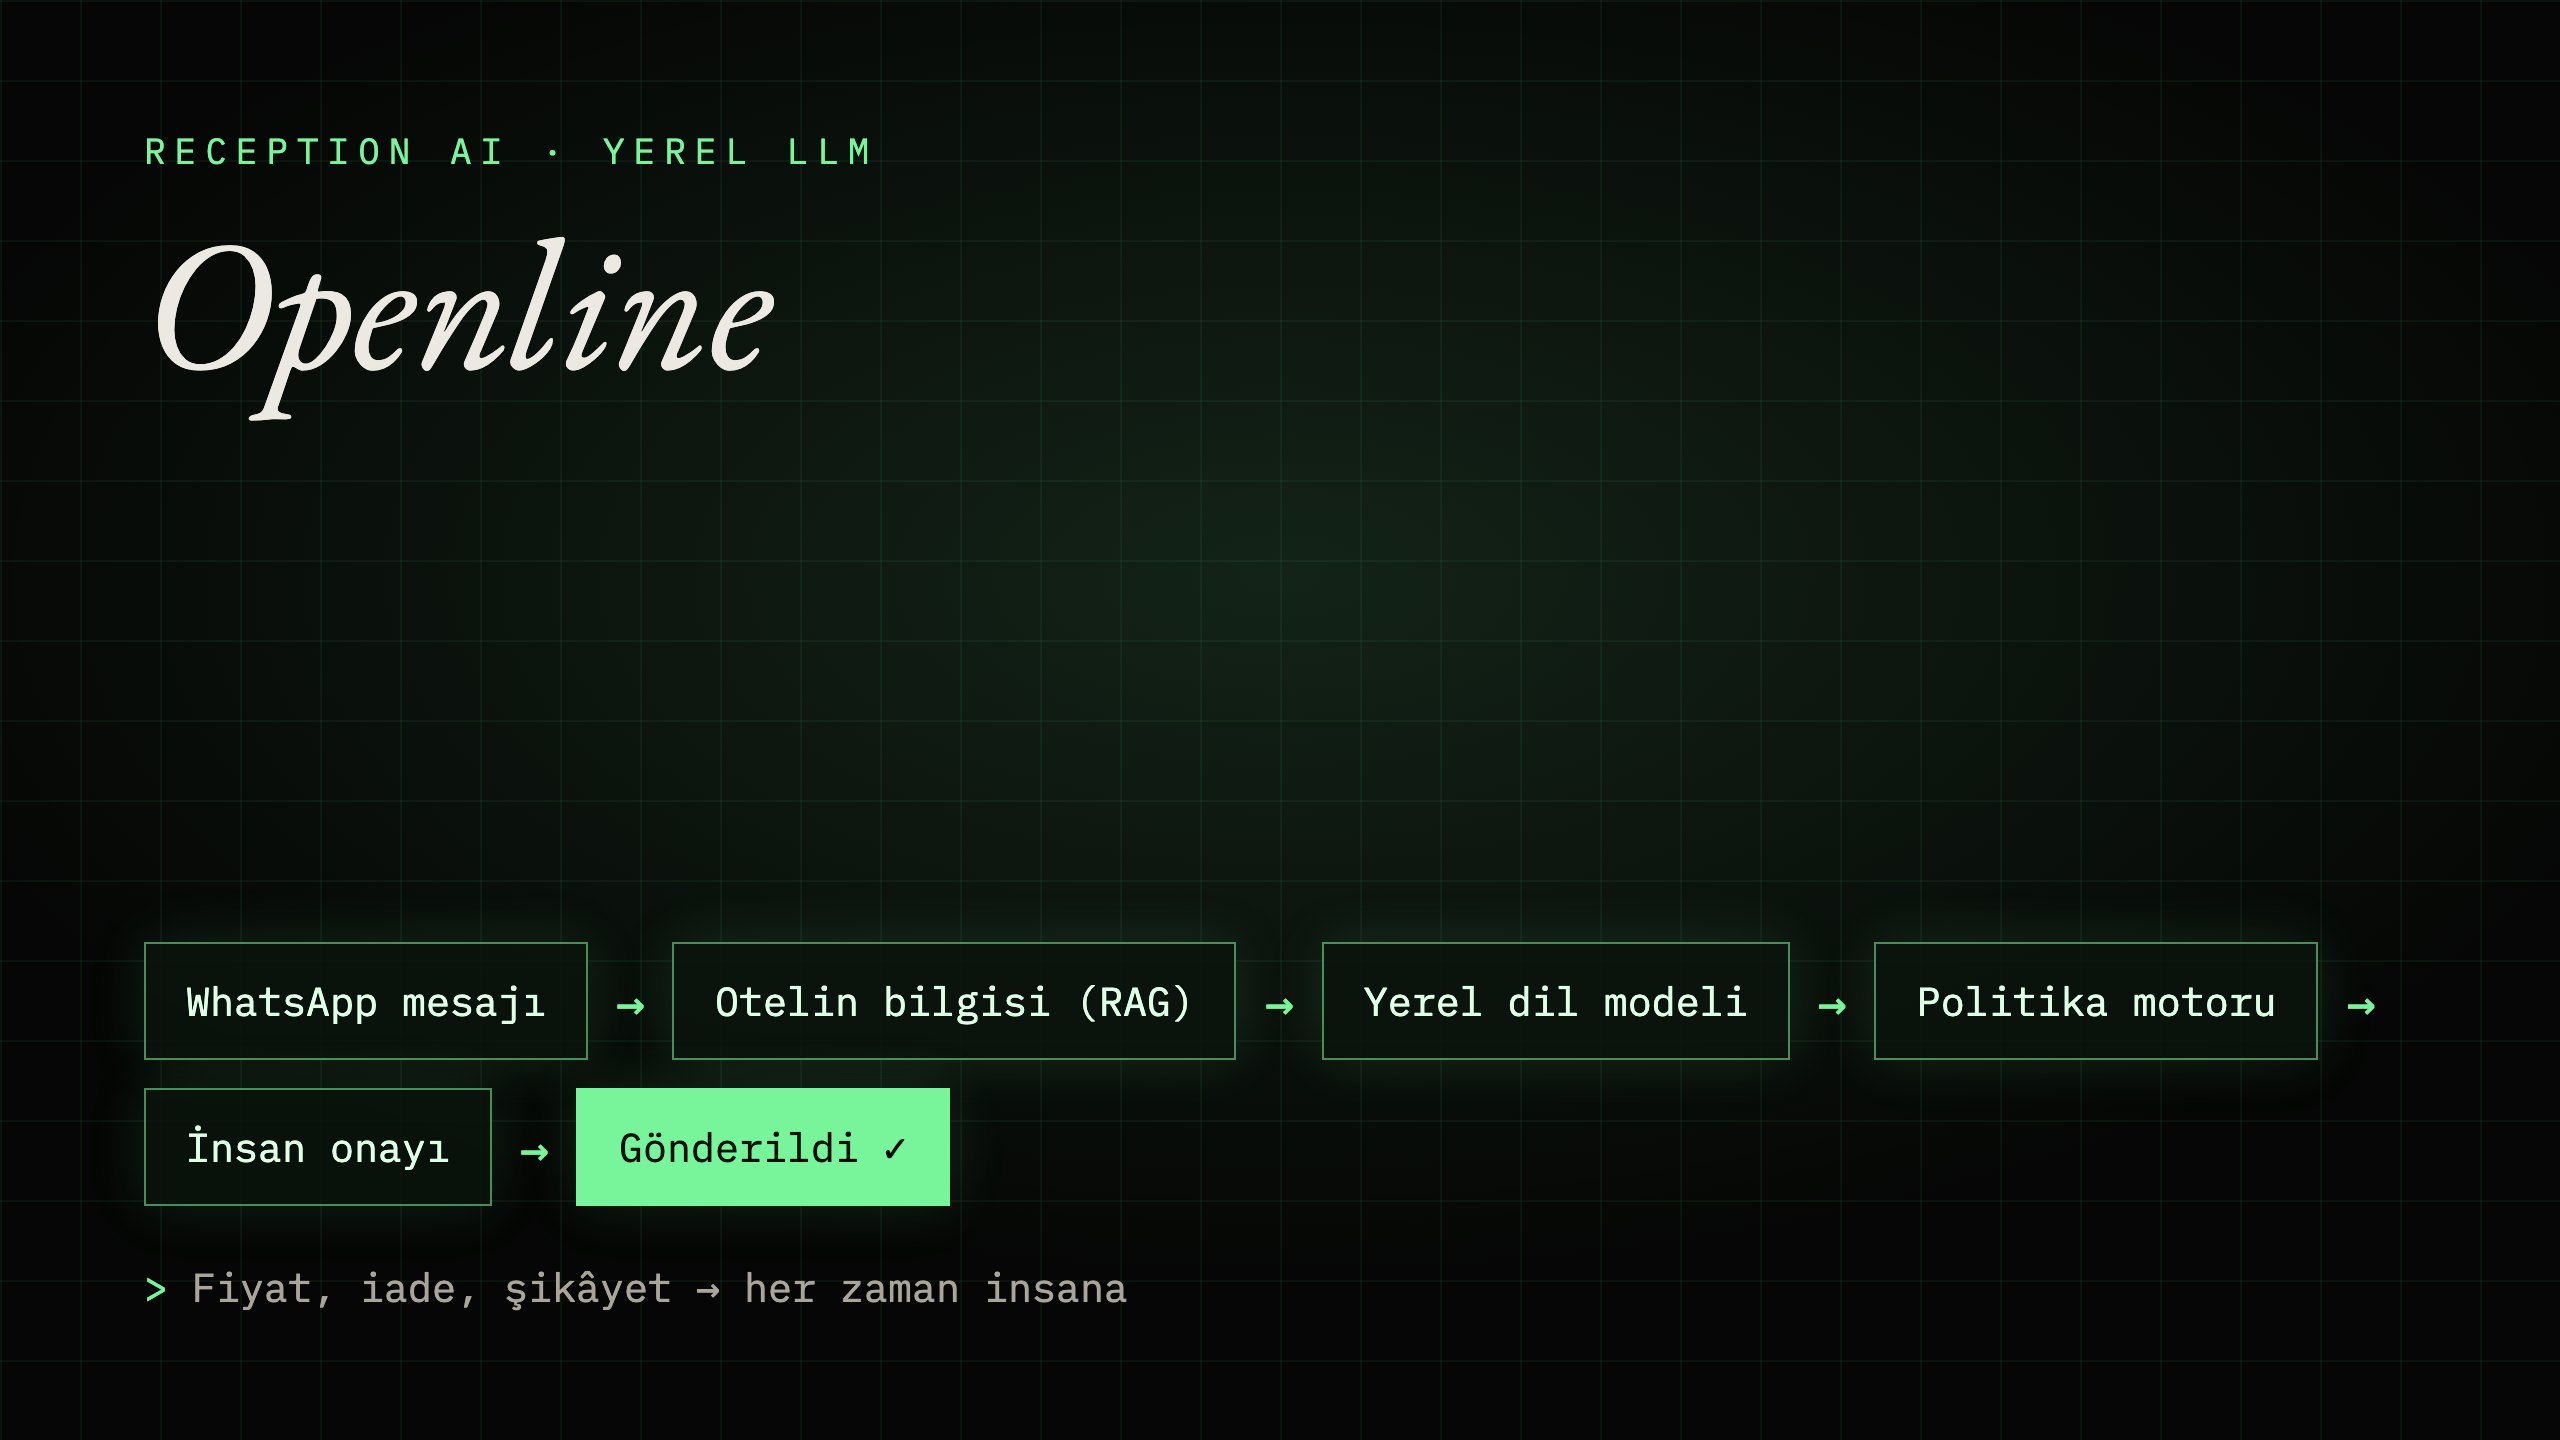
Openline
AI · Hotel WhatsApp Receptionist